Last updated: October 6, 2026
TL;DR The Palantir Ontology turns raw datasets into the things your business actually runs on, like orders, suppliers, and assets, plus the actions people are allowed to take on them. It’s the layer that makes Foundry and AIP useful day to day. Most Ontology failures are design failures, not platform failures. Start with one decision and model only what it needs. For the wider program, see our Palantir Foundry and AIP implementation approach.
The Palantir Ontology is Foundry’s operational layer. It models a business as objects, links, and actions, so people, apps, and AI agents read and change one governed version of reality. Think digital twin, but one you can act on.
Skeptics say the Palantir Ontology is just tables and foreign keys with a nicer interface. They’re half right. The half they miss is the whole point.
Tables can tell you a shipment is late. They can’t reassign the stock, warn the warehouse, or record who made the call. The Ontology can, because it keeps the decisions a business makes next to the data they depend on, which is why Palantir’s own Architecture Center says the system was built to represent the interconnected decisions of an enterprise, not simply its data.
Why care? Gartner estimates poor data quality costs organizations an average of $12.9M per year. Bad data is expensive. Bad data someone acts on is worse.
Below, I’ll cover what the Ontology is, how its parts map to data you already have, one decision traced from dataset to writeback, a fair answer to the skeptics, and design rules that hold up in real operations. I lead PAL4C’s Foundry and AIP delivery practice. Bias included.
What Is the Palantir Ontology?
Put simply, the Palantir Ontology is a model of your business that sits on top of your data in Foundry. It defines the things you manage, how they connect, and the actions people and AI agents can take on them.
Per Palantir’s Ontology overview, it’s the operational layer for the organization. Two halves. The semantic half covers objects, properties, and links, the nouns of your business. The kinetic half covers actions, functions, and dynamic security, the verbs plus the rules about who gets to use them.
Why does the split matter? Most data platforms stop at the semantic half. They’ll tell you what exists. They won’t let you change it from the same place, under the same permissions, with a record left behind for the next person, and that’s exactly the gap the Ontology closes. It’s also why Palantir pitches it as a digital twin aimed at better decisions at scale, not prettier dashboards.
In plain terms? Planners stop exporting CSVs to make a call. They make it inside the model.
Palantir CTO Shyam Sankar put it bluntly in a line quoted by Sherwood News in 2025. “Our advantage comes down to Ontology.” Interested party, sure. Still, it tells you where Palantir thinks the value lives, and our Palantir Ontology services page shows how PAL4C scopes that work for enterprise teams.
What Are the Building Blocks of the Palantir Ontology?
Eight concepts carry most of the weight. Object types, objects, properties, link types, action types, functions, object sets, and interfaces. Each one maps to something a data team already knows, so the learning curve is shorter than it looks.
Start with the official mapping from Palantir’s core concepts reference. A dataset backs an object type. Each row becomes an object, each column becomes a property, each field value becomes a property value, and a join between two datasets becomes a link type that connects their objects.
| What your data team has today | Ontology concept | Logistics example |
|---|---|---|
| Dataset | Object type | Shipment, from the transport system |
| Row | Object | Shipment SHP-20931 |
| Column | Property | estimated_arrival, carrier, status |
| Field value | Property value | estimated_arrival set to November 14 |
| Join or foreign key | Link type | Shipment fulfills Purchase Order |
| Stored procedure or app form | Action type | Transfer Inventory, Expedite Shipment |
| Business logic in SQL or Python | Function | Days of cover per SKU per site |
| Saved filter or query | Object set | All late shipments bound for the Dallas DC |
| Shared schema across tables | Interface | Facility, shared by Warehouse and Port |
Top five rows? Straight from Palantir’s docs. The bottom four are my analogies. That’s where people trip.
Functions are code that runs against objects, which is how you put a calculation like stockout risk in exactly one place instead of fifteen dashboards. An action type, per the action types documentation, is a set of changes to objects, property values, and links that a user makes in one go, and it can fire side effects such as notifications and webhooks. Interfaces describe a shape several object types share, so a Warehouse and a Port can both behave as a Facility. Property types stretch past strings and integers into geospatial and time series data, per the type reference.
Short version? If you’ve built a star schema, you can read an Ontology in an afternoon. Designing a good one? Much longer.
How Does the Ontology Turn Data Into a Decision? A Worked Example
Definitions only go so far. Let’s follow one decision.
Fair warning. This is an illustrative scenario, not a client record.
It’s a Tuesday. A carrier feed pushes an updated ETA for shipment SHP-20931, 4,000 units of a packaging SKU moving from a supplier in Rotterdam to a distribution center in Dallas. New ETA? Six days late.
Rows Become Objects
In a typical warehouse, that update is a changed value in row 48,112 of a shipments table, and nobody notices until Thursday’s report runs. In the Ontology, that same row is a Shipment object with an estimated_arrival property, and the new date shows up in every app, agent, and alert reading that object as soon as the pipeline syncs. That pipeline is unglamorous work. It’s also most of what our data integration and engineering team does in the first weeks of an engagement.
Links Supply the Context
Shipment links to Purchase Order. Purchase Order links to Supplier and SKU. The SKU links to inventory at Dallas and at a second site in Memphis. One hop at a time, the object graph answers questions that would otherwise take four SQL joins, two spreadsheets, and a long email thread between procurement and the warehouse team in Dallas. Which customer orders depend on this SKU? Is there spare stock in Memphis? Who owns the supplier?
A Function Scores the Risk
A function calculates days of cover at Dallas. Say it drops from 9 days to 3. Anything under 5 gets flagged. Same logic everywhere.
An Agent Proposes and a Planner Decides
Now AIP steps in. An agent picks up the flagged objects and drafts options. Expedite by air. Transfer 1,500 units from Memphis. Split the order with a backup supplier in Monterrey. In this setup the agent can’t execute any of them alone, because the only changes it can make are action types that need a human sign-off from someone with the right permissions.
Our planner picks the Memphis transfer. One click.
The Action Writes Back
That click runs an action type, call it Transfer Inventory. Edits land in a writeback dataset, and the side effects fire. A webhook tells the warehouse management system to pick the stock. A notification reaches the Dallas site lead. The decision, the person who made it, and the data they were looking at all stay attached to the objects, so when someone asks in December why Memphis ran short, the answer is already sitting there.
Data, objects, links, logic, action, writeback. That’s the loop.
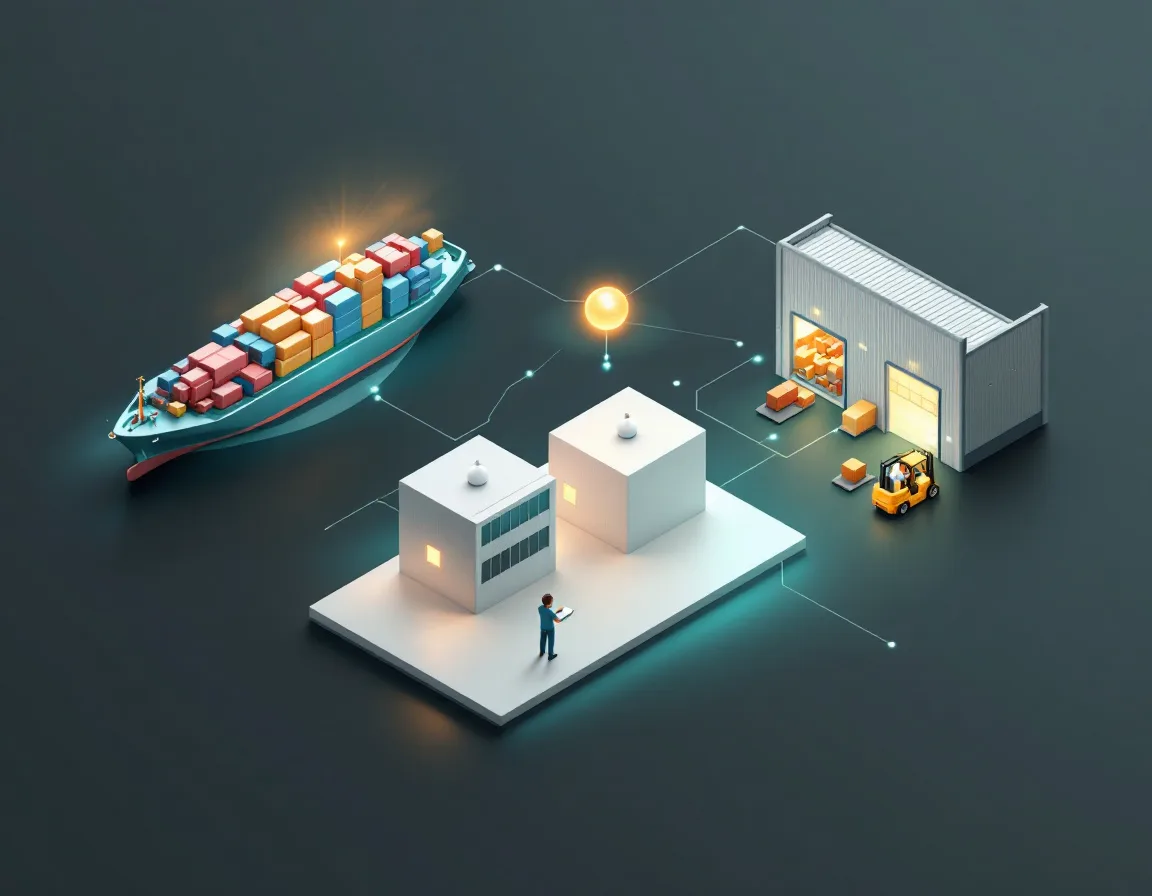
Messier in real life, same mechanics. In a PAL4C engagement with a global logistics operator, the starting point was 18 disconnected warehouse and inventory systems. We built a Foundry Ontology unifying supplier, inventory, and logistics data, then added AIP-powered demand forecasting agents that trigger procurement actions. Procurement delays fell 34%. Annual savings hit $12M. Full cross-region visibility came in the first quarter, the whole build ran five months from kickoff to deployment, and the anonymized write-up sits on our case studies page.
Isn’t the Palantir Ontology Just a Data Model With Extra Steps?
Structurally, it’s close. Object types look like tables, properties like columns, links like foreign keys. The difference is what sits on top. Actions, writeback, and security down to individual properties turn a read-only model into an operational one.
Vonng makes the sharpest skeptic case in a 2026 post, mapping object type to table, property to column, link to foreign key, and action to stored procedure. Fair enough. I’d sign off on most of that myself.
Where the argument thins out is everything a stored procedure doesn’t give you for free. It doesn’t know that one planner may move stock out of Memphis but not out of Monterrey. It doesn’t attach the edit to an object history a non-engineer can read. It doesn’t present itself to an LLM as a governed tool with typed parameters and approval rules. And it doesn’t come with permissions enforced at the object, property, row, and column level out of the box, which is exactly how Lokad’s otherwise critical 2026 review describes Palantir’s security model.
Could you build all of that on Postgres? Sure. I’ve watched teams try, and the ones that finish tend to end up with something that looks suspiciously like an Ontology, minus the tooling, plus a maintenance bill nobody budgeted for.
So is it a data model with extra steps? Yes. The extra steps are the product.
How Does the Ontology Compare to a Semantic Layer or Knowledge Graph?
A semantic layer standardizes metrics for reading. A knowledge graph standardizes meaning for reasoning. The Palantir Ontology does a version of both and adds governed write actions, which neither of the other two is built for.
On the metrics side, the dbt Semantic Layer, powered by MetricFlow, lets you define metrics on top of existing models so every tool reports the same revenue number, and Databricks offers a similar idea through Unity Catalog metric views, which Atlan describes as measures and dimensions you define once and reuse. Knowledge graphs built on W3C’s OWL 2 treat an ontology as a formal vocabulary of terms shared by a community.
| Approach | What it models | Read or write | Built-in actions | Role for AI agents | Best for |
|---|---|---|---|---|---|
| Palantir Ontology | Objects, links, actions, functions, interfaces | Read and write | Yes, action types with side effects | Objects as context, actions as governed tools | Operational decisions by people and agents |
| Warehouse ERD or star schema | Tables, keys, relationships | Read only | No | Raw tables to interpret | Reporting and BI |
| dbt Semantic Layer | Metrics, dimensions, and entities on dbt models | Read | No | Consistent metric definitions to query | One version of each metric across BI tools |
| Unity Catalog metric views | Measures and dimensions | Read | No | Reusable metrics inside Databricks | Teams standardized on Databricks |
| OWL or RDF knowledge graph | Classes, properties, formal axioms | Mostly read | Not natively | Shared vocabulary and inference | Shared vocabularies and research data |
Pick by the job, not the logo. Three dashboards showing three revenue figures? A semantic layer is cheaper and faster. Honestly, you probably don’t need Palantir for it, and our analytics and decision intelligence work would start there. Decisions made in email with no trail? A metrics layer won’t touch that. Knowledge graphs earn their keep where inference over a formal vocabulary matters more than writeback. None of these are mutually exclusive, either. We’ve fed Ontologies from dbt models without drama.
How Does Palantir AIP Use the Ontology?
AIP treats Ontology objects as context and action types as tools. An agent reads governed objects, reasons with an LLM, and proposes or runs actions only within the permissions and approval rules the Ontology already enforces.
Three build tools matter here, per Palantir’s AIP overview. AIP Logic for LLM-backed functions, AIP Chatbot Studio (formerly Agent Studio) for agents, and AIP Evals for testing them. All three sit on the Ontology. None replace it.
Buyers underrate this part. An LLM pointed at raw tables has to guess what a column called STS_CD means, and it’ll guess with total confidence. Point the same model at a Shipment object with a status property, a supplier link, and an Expedite action capped at a set cost, and there’s far less left for it to guess. Garbage objects in, confident garbage out.
Augmentation first, automation later. That’s roughly how Palantir’s architecture material frames humans and agents sharing one system. In practice, agents draft and humans approve for the first few months, and you loosen the leash one action type at a time as AIP Evals results hold up against real cases. Our AIP AI agents practice builds exactly that progression. Newer to the platform? Start with what Palantir AIP actually does.
How Do You Design a Palantir Ontology That Survives Operations?
Start from decisions, not source systems. Pick one decision, model only the objects and actions it needs, give every object type a stable primary key and a named owner, and expand after that first workflow is in daily use.
Mirroring source systems is the most expensive mistake we see. Eighteen systems become eighteen sets of object types, and the Ontology quietly inherits every silo it was meant to remove.
Here’s the checklist we run before anyone opens Ontology Manager.
- Write down the three decisions this Ontology should change. Can’t name them? Stop here.
- Primary keys. Stable, unique, never recycled, because a shipment ID that a carrier reuses every 90 days will silently fold two shipments into one object.
- One owner per object type, by name, on the business side.
- Would an interface help? If Warehouse, Port, and Cross-Dock all need the same capacity logic, define a Facility interface once.
- Actions before apps. Agree on what people can change, and who approves it, before anyone builds a Workshop screen.
- Treat names as permanent, since the property you label in week two will still be in production in year three.
Week six is the usual danger zone. A second team wants their source system modeled too, nobody on the steering group has the authority to say not yet, and the scope of the first release quietly doubles overnight. Guard the first use case like it’s the only one. For a few months, it is.
Once the model holds, the apps follow. Palantir’s Ontology documentation names Object Explorer, Quiver, and Workshop as the tools that sit on top, and Workshop is where our operational application builds pick up.
Where the Ontology Isn’t the Answer
Bias disclosed. We get paid to build these. So read this as the part of the pitch I’d rather skip.
Speed first. Sherwood reported that Ontology builds take weeks and even months, and that effort is exactly what creates switching costs, because nobody wants to rebuild a model their planners and agents already run on. Good for Palantir. Worth pricing in for you.
Decision science is the second gap. Lokad’s critique is that Palantir hosts decisions but doesn’t supply the domain decision science behind them. Fair. The Ontology will execute a bad reorder policy just as faithfully as a good one, so the forecasting and optimization logic still has to come from your own team or a specialist.
Then there are the pipelines. In the setups we build, most data is synced into Foundry and indexed for the Ontology rather than queried live in the source. More to own. More latency to plan around.
And for pure reporting? Overkill.
Where to Start With Your Ontology
Three things to keep. The Ontology is where data becomes something you can act on. Its building blocks map cleanly to what your data team already knows, so the hard part is design, not syntax. And the payoff arrives when people, applications, and AI agents work off the same objects and rules.
PAL4C Labs is a consultancy that works only on Palantir Foundry and AIP. We help enterprise data and operations leaders turn scattered systems into Ontologies and AI workflows that people actually use, and that single-platform focus is the whole reason we exist.
Before modeling a single object, write down the three decisions it should change. Want a second set of eyes on that list? Our Ontology design and build team can pressure-test the model before it hardens. The Foundry implementation phases and timelines guide covers what comes after, and you can walk us through your first use case whenever you’re ready.
Ontology Questions We Hear Most
So Is the Palantir Ontology Basically a Knowledge Graph?
Close cousin, different job. A knowledge graph built on standards like OWL is designed for shared vocabularies and inference. The Palantir Ontology is designed for operations, so it adds action types, writeback, and fine-grained permissions that let people and AI agents change the data, not just query it.
Ontology or Semantic Layer, Does the Gap Actually Matter?
Only if you need to act on the data. A semantic layer like dbt or Unity Catalog metric views keeps metric definitions consistent for reporting. The Ontology does that and lets users take governed actions that write back.
Realistically, How Long Does It Take to Build an Ontology?
Weeks for a first use case, months for anything enterprise-wide. Our logistics engagement went from kickoff to deployment in five months across 18 source systems. The variable that matters most is data access, not modeling. If it takes three weeks to get a firewall exception for the warehouse system, that’s three weeks no amount of Ontology skill can recover.
Who Should Own the Ontology Once It’s Live?
Business teams, with engineering on call. Each object type needs a named owner who can say what a Shipment or a Supplier means, while the data team owns the pipelines feeding it.
Can You Change the Ontology Later Without Breaking Everything?
Mostly. Adding object types, properties, and links is routine. Renaming or removing things that applications, functions, and actions already depend on is where it hurts, so treat names like public APIs from day one.
Does AIP Work Without an Ontology?
Parts of it run, but you’d be throwing away the reason to buy it. AIP Logic, AIP Chatbot Studio, and AIP Evals are built on top of the Ontology, so agents without one have no governed objects to read and no approved actions to take. That’s an expensive chatbot. If AIP is on your roadmap, budget for Ontology design first.